Features
Everything you need.Nothing you don't.
Two products, one identification engine. GalleryID Desktop captions the photos already on your Mac or PC, with nothing uploaded. GalleryID Cloud is the hosted archive you search by athlete name. Each capability below says which product it belongs to.
Want a guided walkthrough? Book a 30-minute demo
Two ways to put a name on a frame.
MatchID finds the athlete. CaptionID names them. CaptionID writes the athlete name and the full caption line from the roster bound to that folder or gallery, at one press or from a shortcode, with no headshots indexed at all. MatchID is the accelerator on top of it: facial recognition matched against headshots you indexed, plus jersey number reading for the frames where the face is not legible. The bound roster narrows who a face could be, and the result is a confidence-scored match per detected face.
You set the confidence threshold. Matches above it write without you. Anything below it waits in the review queue, so you decide what ships. In GalleryID Desktop all of this runs on your own machine. In GalleryID Cloud it runs against the gallery you uploaded.
Names are confirmed. Never guessed.
Match results · sample gallery
Names write to the file.
Approved names write to the file in XMP, with the legacy IPTC-IIM mirror alongside, across the fields you mapped including Persons Shown and Personality. Those are the fields Photo Mechanic, Lightroom, Capture One and Photoshop already read. Open a delivered file and the names are there. No plugin, no integration, no re-tagging.
That is the difference between a tag in somebody's database and a portable file. Send the photo to a client, a wire service or a newsroom and the names go wherever the file goes, rather than staying behind in a row somebody else owns. GalleryID Desktop writes as you tag; GalleryID Cloud writes on download.
VB_2026_W7_4823.jpg · metadata
XMP is the primary, with the legacy IPTC-IIM mirror for agency tooling and wire services that still read IIM on JPEGs.
Your roster, your data.
Load rosters by team and by season. GalleryID Desktop indexes the headshots locally; GalleryID Cloud holds them in your account. Each athlete's headshot becomes the baseline MatchID matches against. Update mid-season as athletes transfer, change numbers or join the roster, and the next run uses the new list.
You supply the headshots and you keep them. There is no global headshot database, nothing is pooled across customers, and your images are not training data. GalleryID is the data processor. On GalleryID Desktop the headshots never leave your computer at all.
Volleyball roster · VB 2025-26
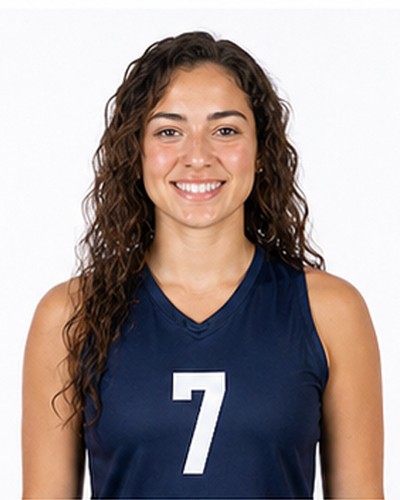 #7Johansson#7 · OH
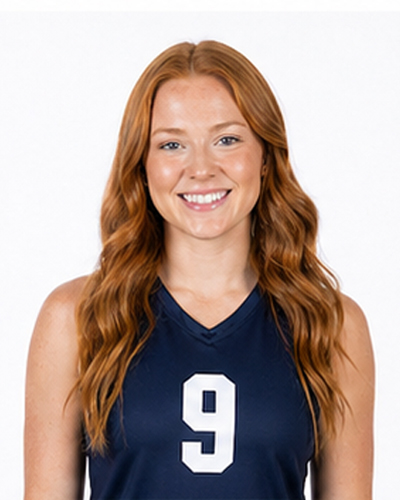 #9Santiago#9 · DS
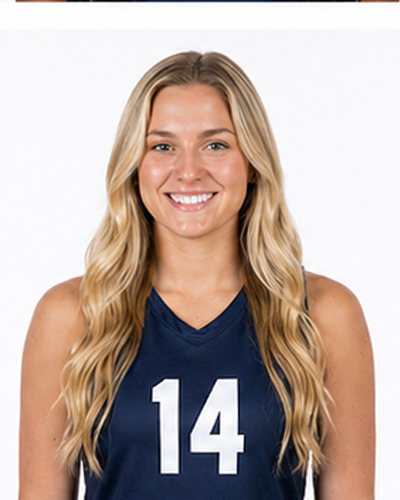 #14Dubois#14 · MB
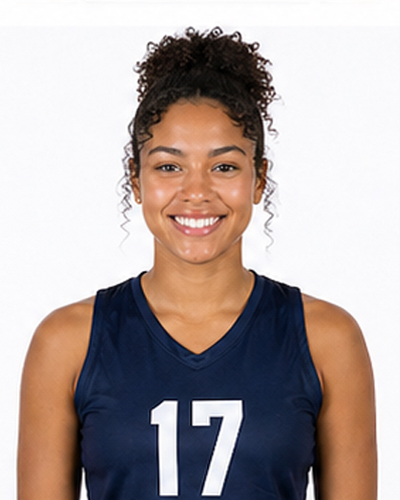 #17Lin#17 · S
 #19Petrov#19 · L
 #21Patel#21 · OH
 #27Yamamoto#27 · L
12 athletes, headshots indexed.
Confirm what is uncertain. Skip what is not.
Matches above your threshold write on their own. Everything below it lands in a queue that shows the photo, the face crop, the suggested athlete and the score, for a one-click confirm or reject. You stay on the uncertain calls instead of paging through the ones MatchID already got right.
Naming one by hand takes the same three routes as anywhere else: pick the athlete from the bound roster, type a CaptionID shortcode that expands into the name and the full caption line, or start typing a name and choose the match. The roster is the source in all three.
A rejected match never reaches the file. You ship what you confirmed.
Review · 4 pending
 0.78 · below thresholdSuggested: Camille Dubois, #14Matched against VB 2025-26
Push anywhere, names already in the file.
Both products deliver over FTP. GalleryID Desktop sends over FTP and FTPS with watermarking and output sharpening chosen per destination, or exports a ZIP with sidecars. GalleryID Cloud pushes to FTP and PhotoShelter destinations you configure once and reuse across galleries. Either way the names are already written to the file, so downstream caption tools and editorial systems have what they need.
No re-tagging at the destination. No caption assembly downstream. The file ships caption-ready.
Delivery destinations
Off the card and into the cull.
Card ingest with token rename, folder patterns, per-folder numbering, and metadata written during the copy rather than in a second pass. About 15 seconds per 1,000 photos copied, 21 to 27 with the metadata written to all of them, across four runs on two Macs. Nothing analyses the photos while the card is copying, so ingest time is copy time.
The cull then runs from previews that already exist: star ratings, colour labels, filters, and Focus check flagging blur and soft focus at four sensitivity levels. RAW is supported throughout, browsing through the JPEG preview the camera embeds in each file. Cull to the keepers, then run MatchID on what survived. The Edit tab handles the deadline pass: histogram, tone curve, white balance eyedropper, clarity and texture, all non-destructive, with edits that copy and paste between frames. Camera voice memos transcribe on your machine and resolve against the roster into suggestions you confirm.
Ingest · CFexpress card
Desktop 1.0.131, figures from the application log. The card ejects at copy-end and the cull starts immediately. Results vary with hardware, card, reader and file type.
Your drives, searchable with nothing plugged in.
The Catalog indexes whole drives into an archive you can browse offline. Search by name, keyword or filename with the drives unplugged, and export HD previews or originals with people, keywords and capture date already written to them. It reads the names written to your files, including years of tagging done in other software, so the archive is searchable the day you index it.
Removing an item from the Catalog never touches the source file. Companion apps for iPhone and Android browse the Catalog over your own wifi only, so the archive rides along without going near a server.
Catalog search · drives unplugged
“Patel” returns frames from all three, mounted or not.
Your brand. Your URL. Your gallery.
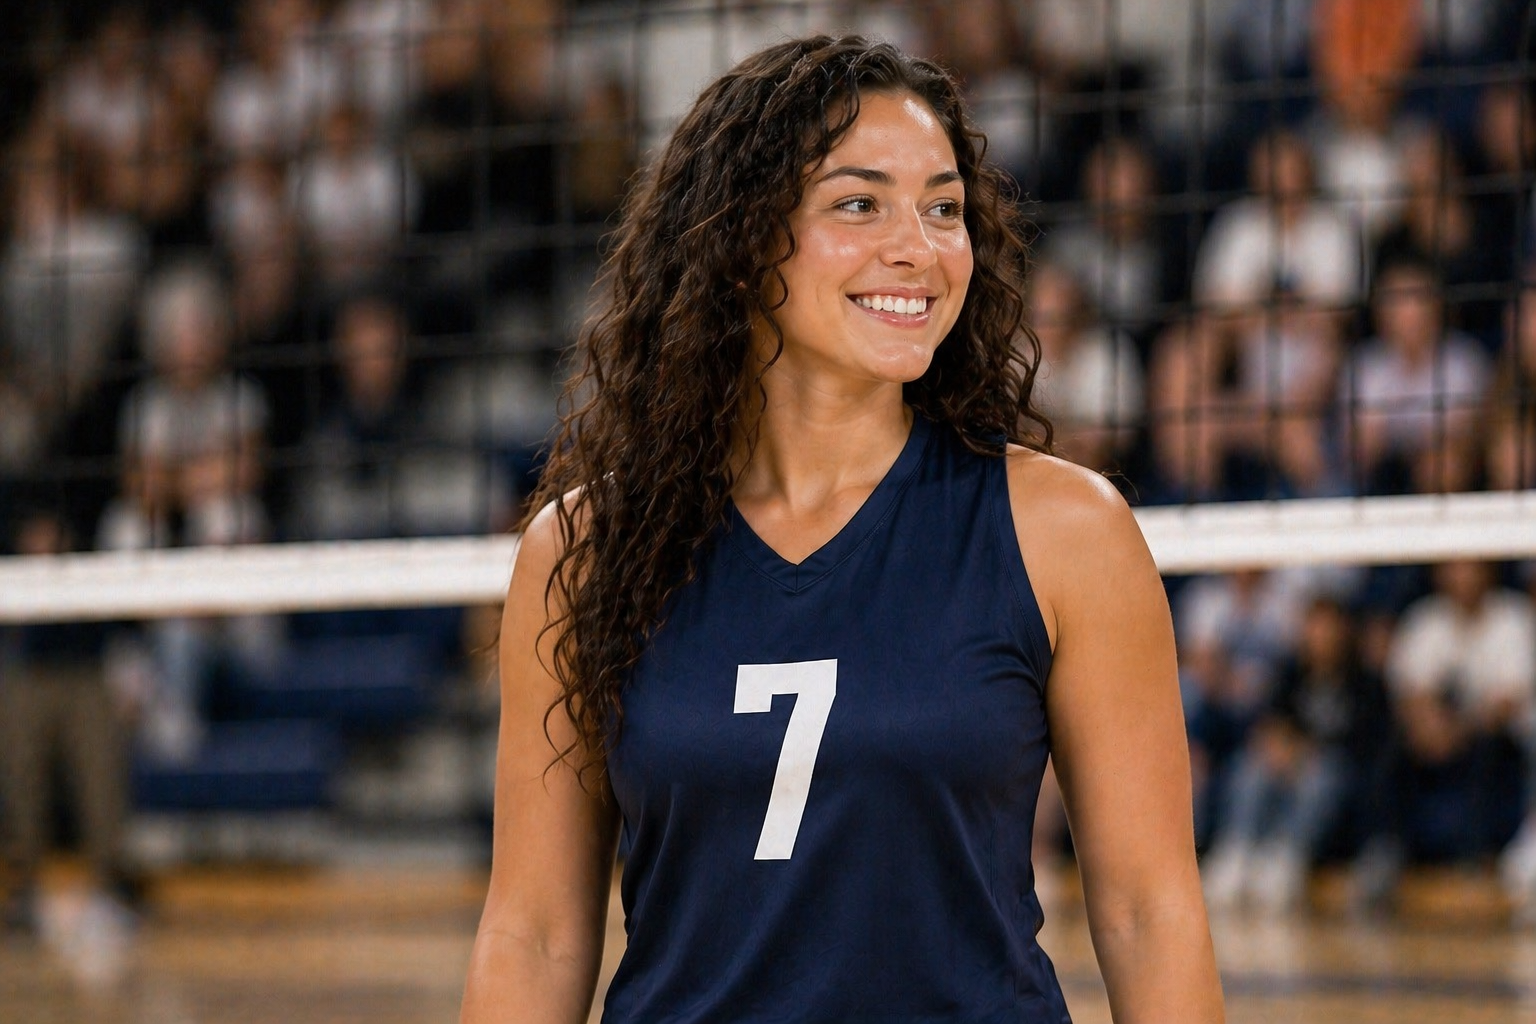
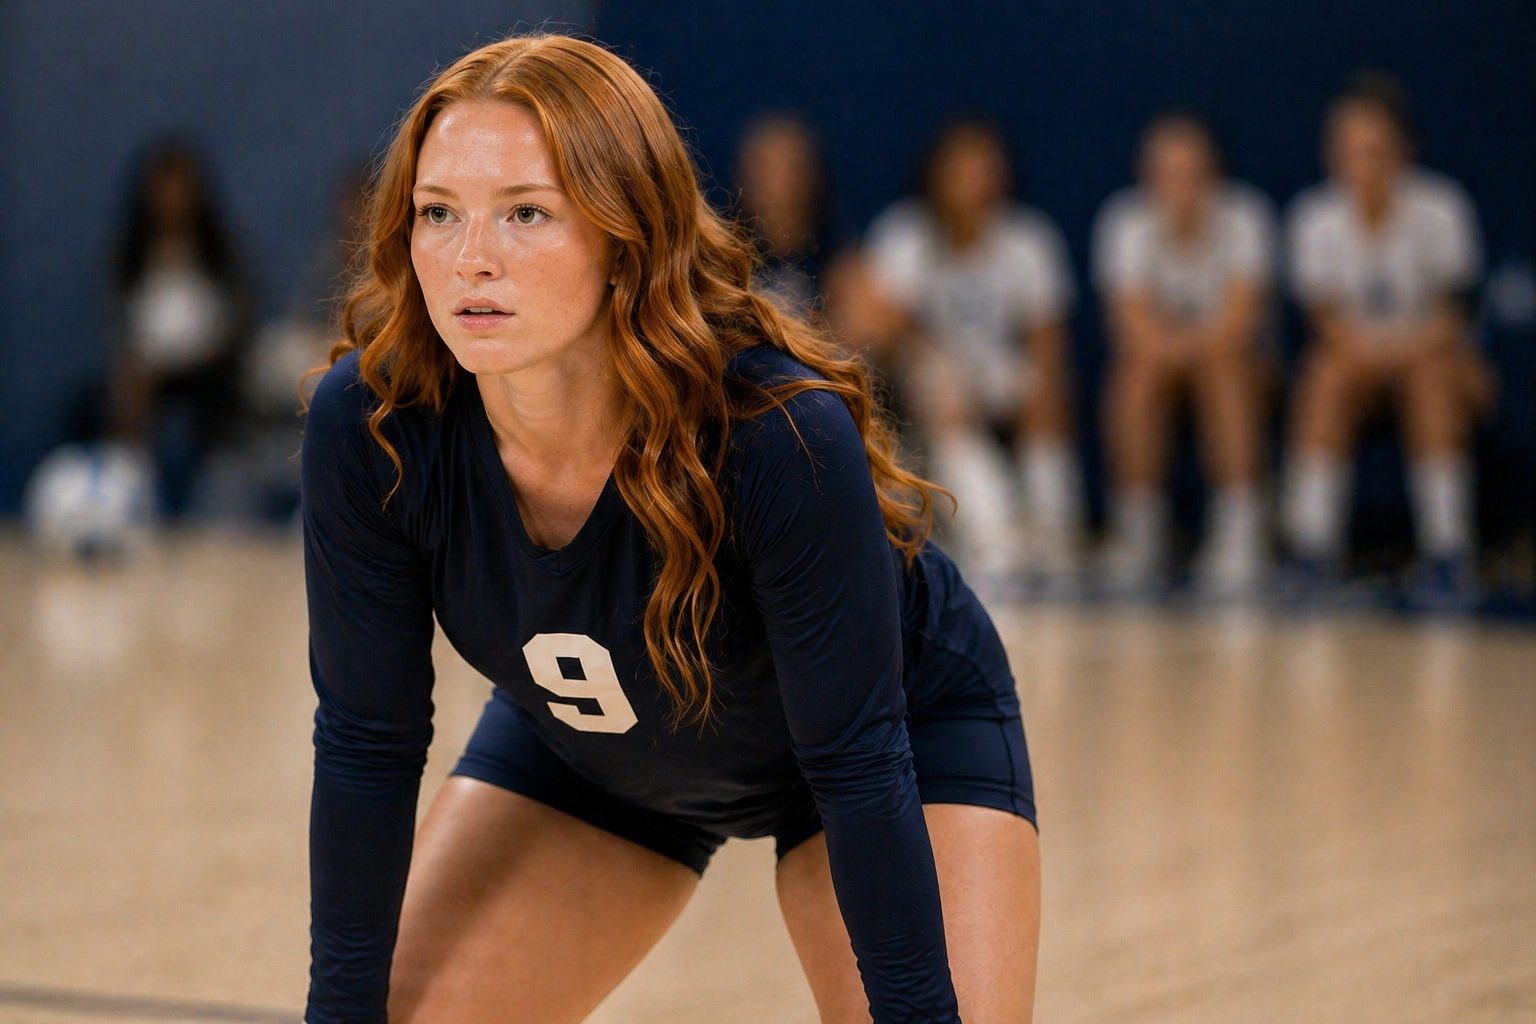
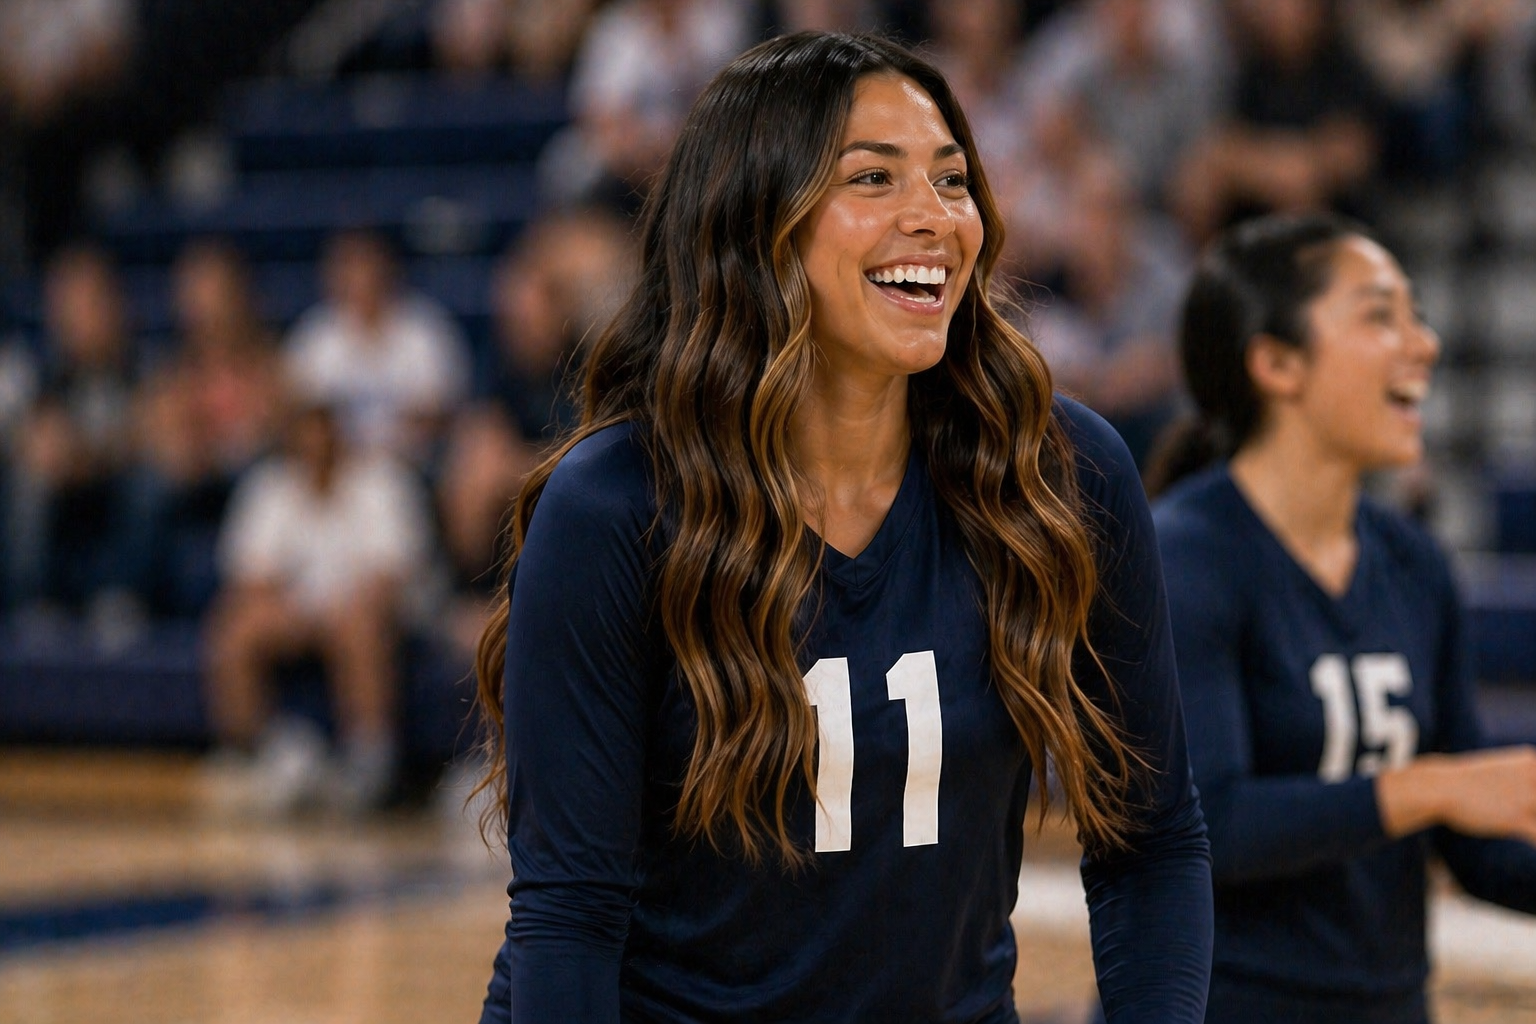
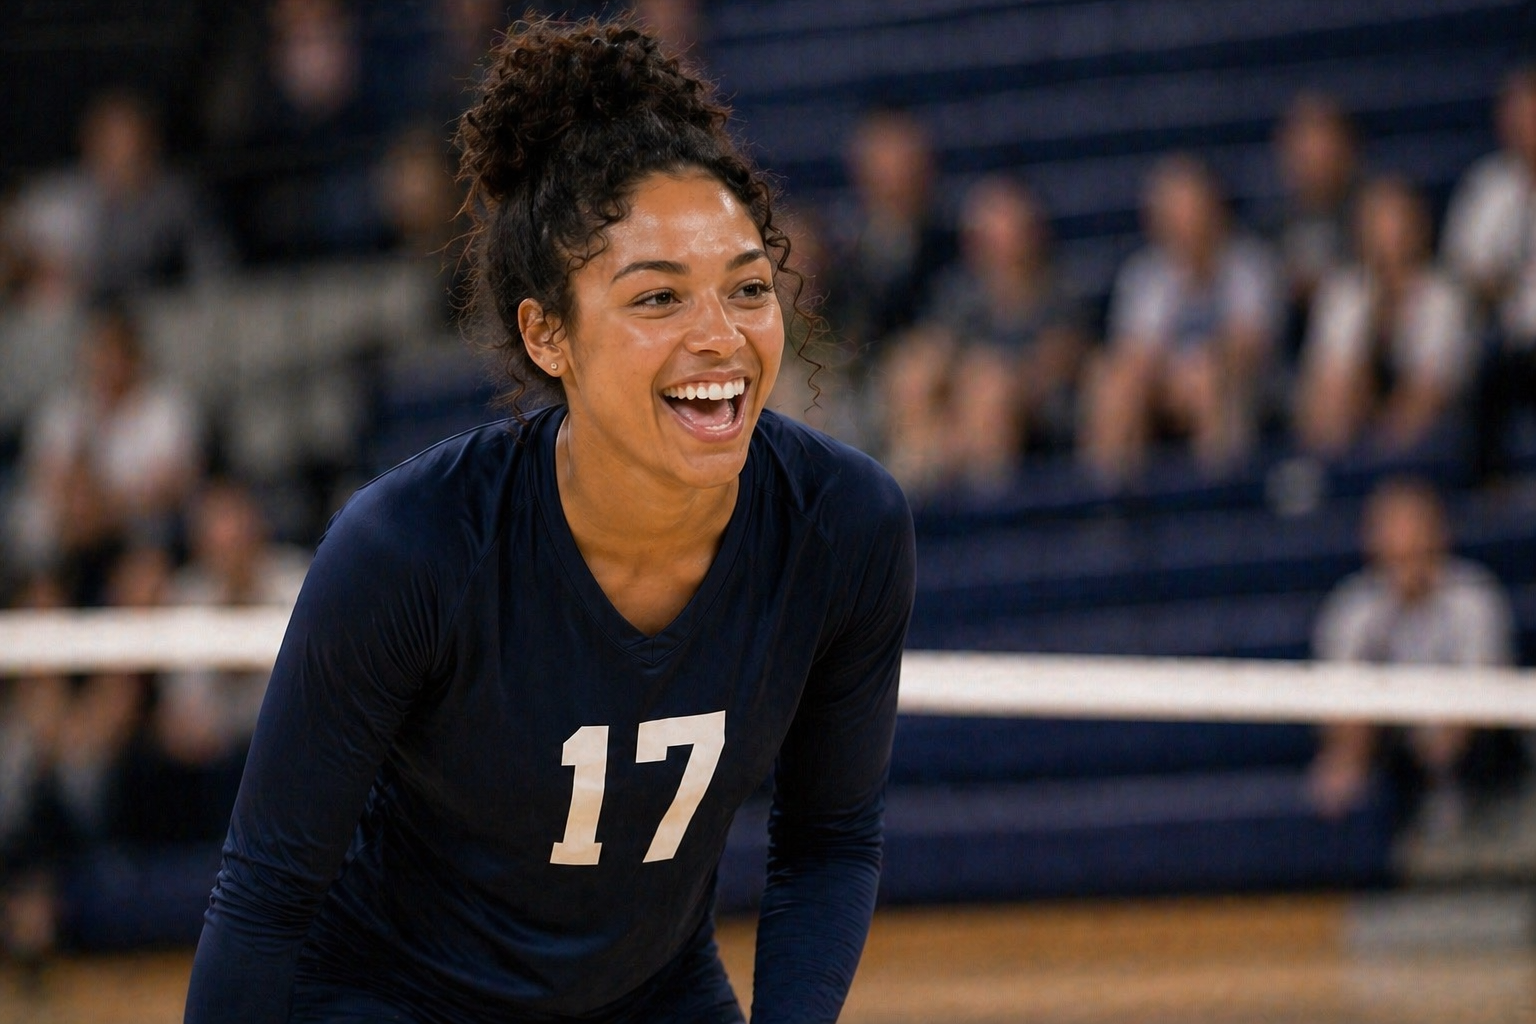
Public, private or password-protected galleries, with custom domains, custom branding and custom expiry dates. On all Cloud plans, not held back for an enterprise tier. Send a link to a client, to the media, or to one athlete.
Permissions are scoped per gallery, so comms gets one view, creative gets another, and alumni get the public one.
Shared gallery
Fans and alumni buy direct. Zero commission.
Per-photo or per-gallery pricing, set once per gallery. Fans, alumni and media buy and download files with the athlete names already in the metadata. GalleryID takes no commission. The proceeds are yours.
Stripe-backed payments and download tokens that expire. A buyer takes one photo or the whole gallery as a single download. Digital only, no prints.
Buyer view
Buy this photo
Maya Patel, #21 · Week 7 vs. Conference Rivals
One athlete. Their full archive. One search.
Once the names are in the metadata the hosted archive is searchable by them. Pull one athlete's photos across games, photographers, sports and seasons: a senior's highlight set for the awards banquet, a multi-year run for the alumni magazine, an athlete's full gallery to send them. One search.
Filter by sport, season, photographer or event, and combine the filters. Export the result as a shared gallery or push it to FTP.
Archive search
Searching"Maya Patel" · 2025-26 season
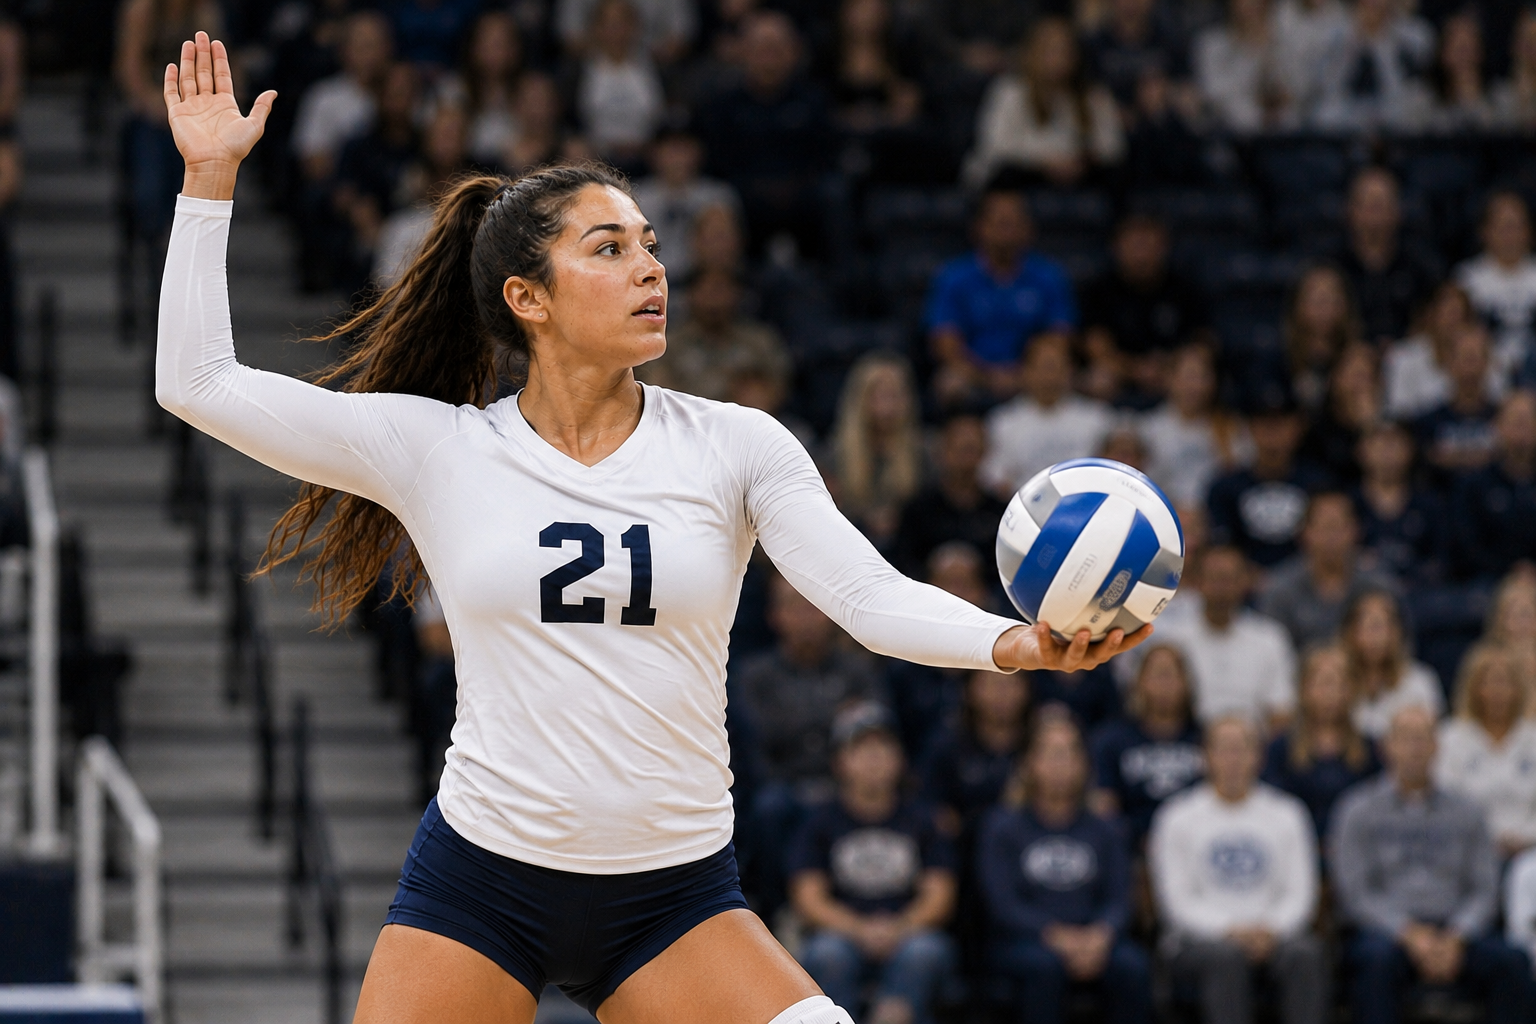
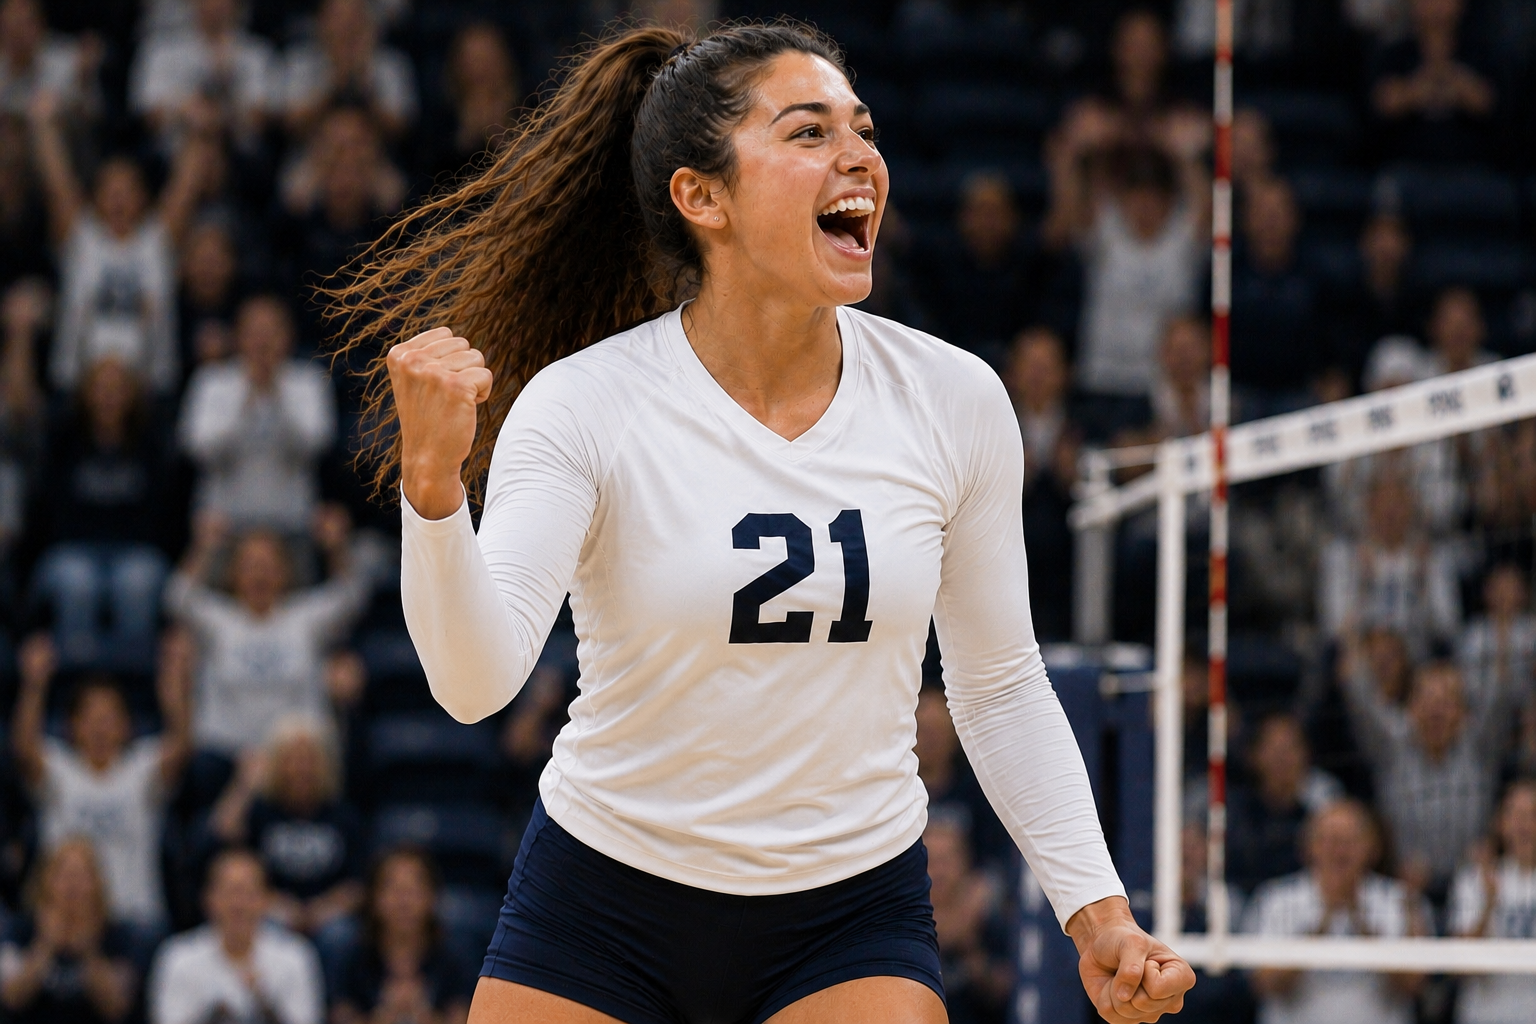
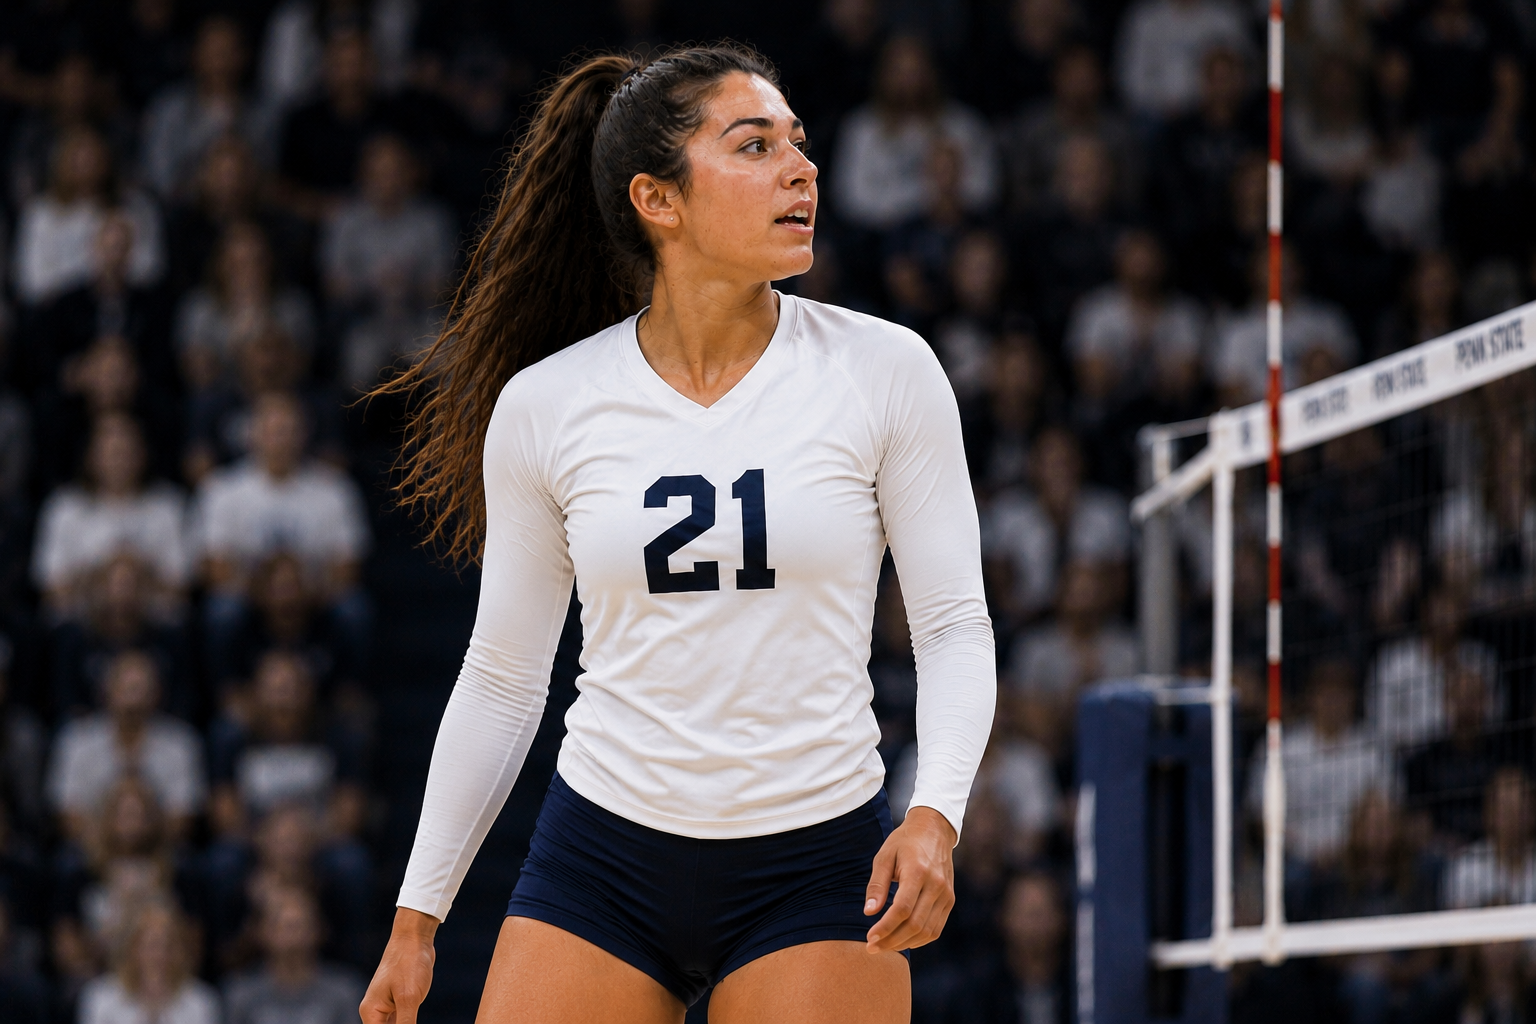
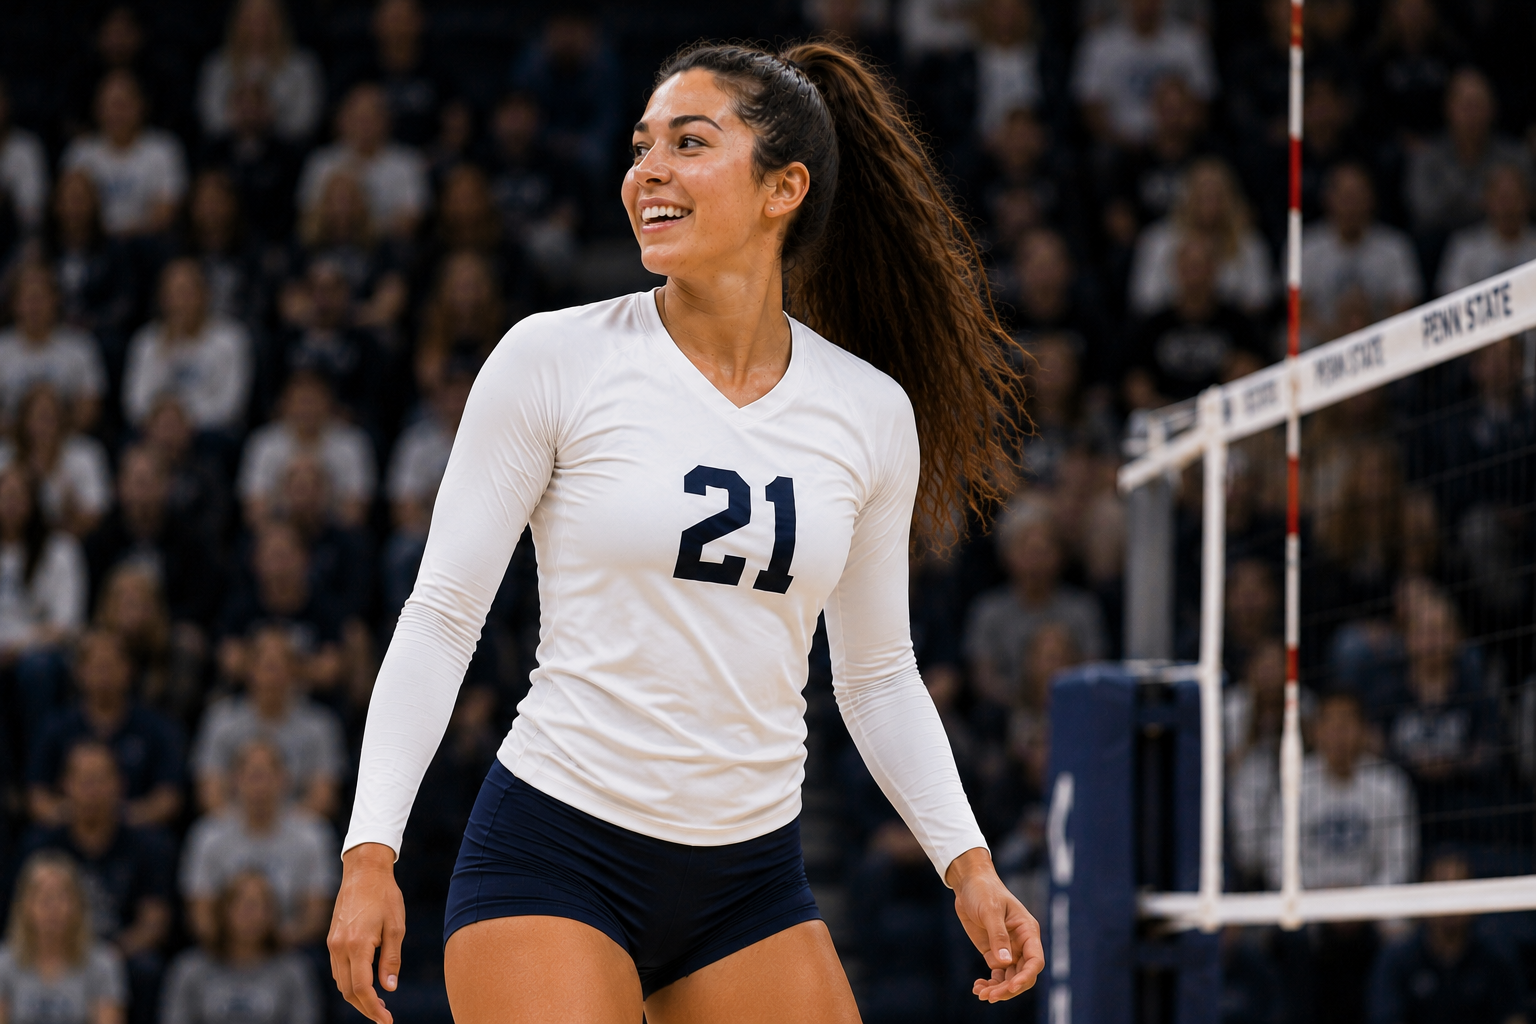
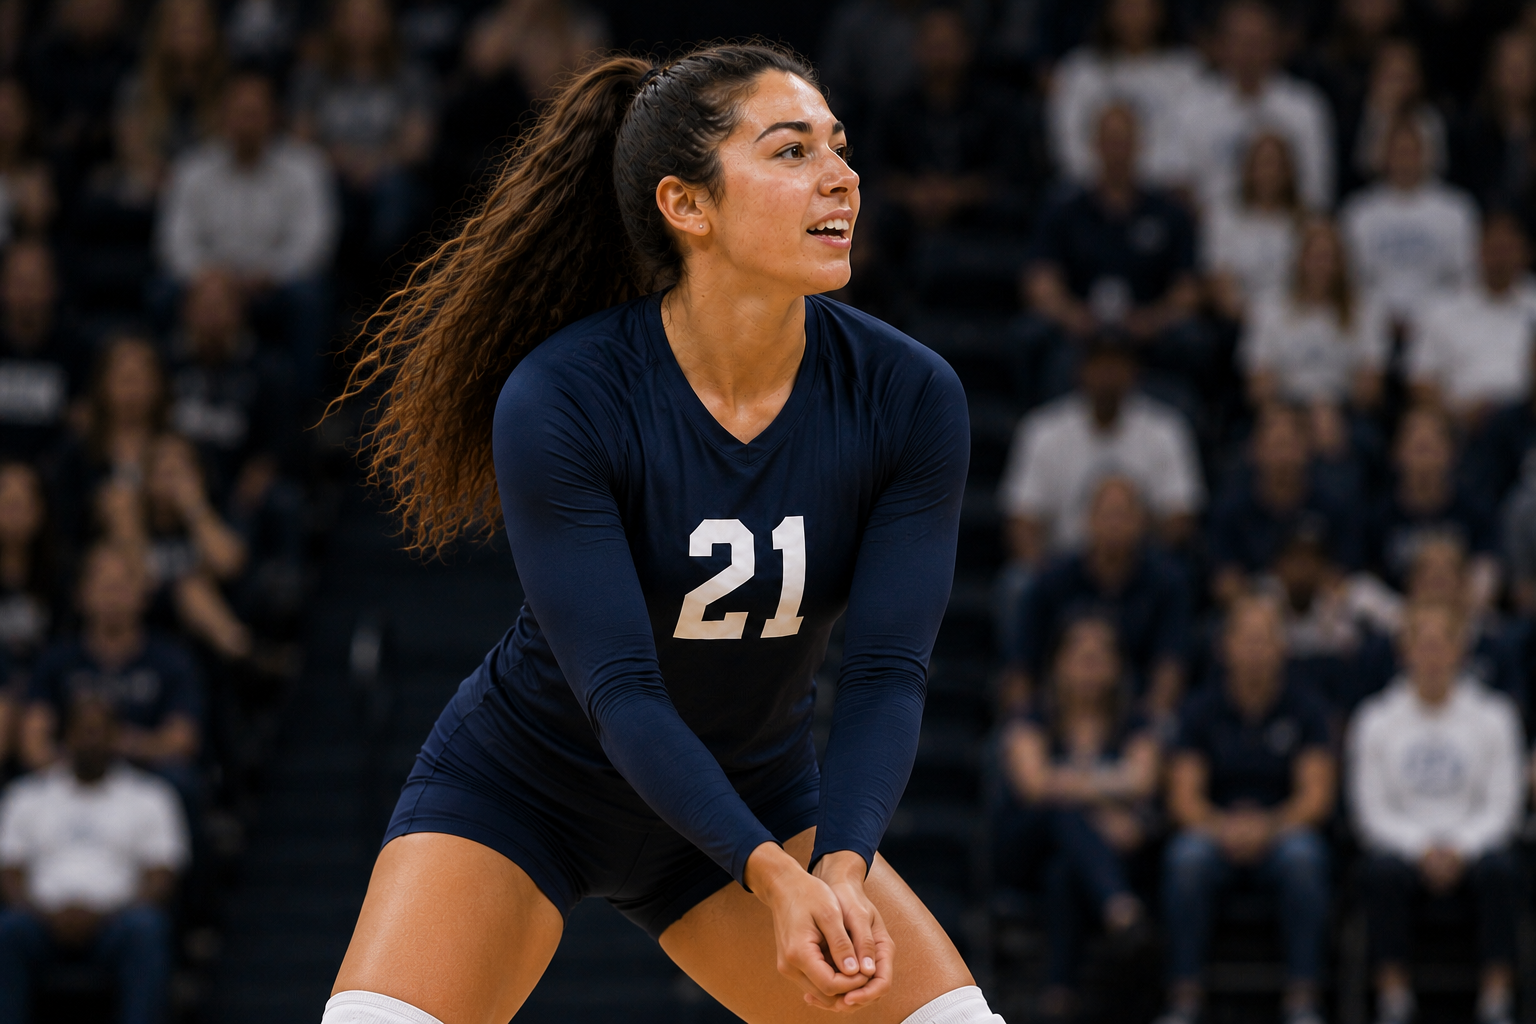
147 photos across 12 events
Staff see what they need.
Five roles: viewer, photographer, editor, client admin and site admin. Photographers see what they uploaded. Comms sees the approved galleries. Creative gets athlete-scoped views. Admins see the whole account with an audit log behind it.
Multi-photographer teams without per-seat charges. For a one-time or occasional contributor you do not want as a user, create a gallery-specific upload link instead. Bring people in as users when that makes sense, and send a link when it does not.
Roles in this account
What people ask about the two products.
Which features are in both products, and which are in only one?
+
MatchID, CaptionID, the confidence threshold and its review queue, roster management by team and season, metadata written to the file, and FTP delivery all run in both. GalleryID Desktop adds card ingest, culling, the Edit tab and the Catalog, and it is where identification runs on your own machine. GalleryID Cloud adds branded galleries, the download store, search by athlete across the archive, role-based access and upload links. Each section on this page says which product it belongs to.
Do I have to upload my photos to use GalleryID?
+
Only in GalleryID Cloud, which is a hosted archive and is meant to hold them. GalleryID Desktop uploads nothing: it works on the photos already on your computer, identification runs locally, and no photo, headshot or face datum is stored on GalleryID servers. The two are independent subscriptions and neither requires the other, so if uploading is the thing you do not want, Desktop on its own is the whole product.
Does identification need reference headshots?
+
MatchID does, because facial recognition has to have something to match against. CaptionID does not. Bind a roster to the folder or gallery and one press writes the athlete name and the full caption line to the fields you mapped, with no headshots indexed at all. That is why the two paths are worth keeping straight: MatchID finds the athlete, CaptionID names them.
What happens to a match the software is not sure about?
+
It waits. You set the confidence threshold. Anything above it can write without you, and anything below it lands in the review queue with the photo, the face crop, the suggested athlete and the score, for a one-click confirm or reject. A rejected match never reaches the file. Names are confirmed. Never guessed.
Where do the names get written, and what can read them?
+
Names write to the file in XMP, with the legacy IPTC-IIM mirror alongside, covering the fields the app maps including Persons Shown and Personality. The names go wherever the file goes, so they read in Photo Mechanic, Lightroom, Capture One or anything else that reads photo metadata, with no plugin and no re-tagging at the far end. GalleryID does not just recognise the athlete, it puts the athlete name into the photo. GalleryID Desktop writes as you tag; GalleryID Cloud writes on download, and the metadata updates whenever the names change.
Does GalleryID keep a headshot database or train on my photos?
+
No to both. You supply your own headshots, they belong to your account or, on Desktop, never leave your computer, and they are used to identify the athletes on your own roster. There is no global face database, nothing is pooled across customers, and your images are not training data. GalleryID is the data processor.
Does my Photo Mechanic work carry over?
+
Yes, both ways. GalleryID Desktop reads existing Photo Mechanic code replacement values, so code sets you already maintain keep working. And GalleryID doesn’t lock your metadata in: names write to the file in XMP and IPTC metadata, so the names go wherever the file goes, and a photo you send to someone on Photo Mechanic opens with the names in place. Star ratings, colour labels and the protect tag sync through XMP in both directions, so Photo Mechanic and GalleryID Desktop see the same values on the same files.
How fast is card ingest on GalleryID Desktop?
+
About 15 seconds per 1,000 photos copied, and 21 to 27 seconds per 1,000 with the metadata written to all of them. Measured at 14.9, 14.9, 15.6 and 16.9 seconds per 1,000 across four runs on two Macs. The largest run was 9,662 files and 101.92 GB from a SanDisk Extreme PRO CFexpress Type B in a ProGrade PG05.5 reader, copied in 2:24 and fully captioned in 3:23 to 4:20, on Desktop 1.0.131, from the application log. Token rename, folder patterns and the metadata write are inside those numbers, because metadata is written to each file as it is written rather than added in a second pass. Results vary with hardware, card, reader and file type.
Do GalleryID Desktop and GalleryID Cloud talk to each other?
+
Not as a built feature. Desktop delivers over FTP and FTPS, and Cloud can be an FTP destination like any other, so photos can go from one to the other the same way they go to a wire service. There is no publish button, no sync and no pipeline between them, and neither subscription requires the other.
What do the two products cost?
+
GalleryID Cloud is priced on storage and nothing else, from $20/mo for 200 GB, with MatchID and users unmetered at any tier. GalleryID Desktop is one flat price, $20/mo or $200/yr, and the subscription covers two computers; identification is unmetered there because it runs on your own machine. Both include a 14-day free trial and both require a card. There is no free plan on either.
Two products.Neither one meters you.
MatchID and CaptionID run in both. GalleryID Cloud is priced on storage alone, with identification and users unmetered at any tier. GalleryID Desktop is one flat price covering two computers, and identification is unmetered there because it runs on your machine.
14 days free, card required. Cancel anytime.